Data Engineering & Analytics
 White-Label & Dedicated Teams - Offshore developers, maintenance and agency support
Headless CMS - Sanity, Payload, Storyblok, Prismic, Contentful, Strapi and Next.js
AI Solutions - AI agents, chatbots, automation and machine learning
WordPress & WooCommerce - Custom themes, plugins and online stores
Shopify & eCommerce - Shopify, BigCommerce, PrestaShop and Webflow builds
HubSpot CMS - Custom themes, modules and integrations
Custom Web Development - PHP, Laravel, CodeIgniter, CakePHP, MERN and MEAN
Mobile App Development - iOS, Android, Flutter and React Native
Business Software - CRM, ERP, SaaS and enterprise applications
UI/UX & Frontend - Figma, design systems and pixel-accurate Figma-to-HTML
Numbers people can trust
Data Engineering & Analytics
Every AI project and every good dashboard starts with the same question: is the data ready? In most companies it is scattered across systems, defined differently by each team and sometimes simply wrong.
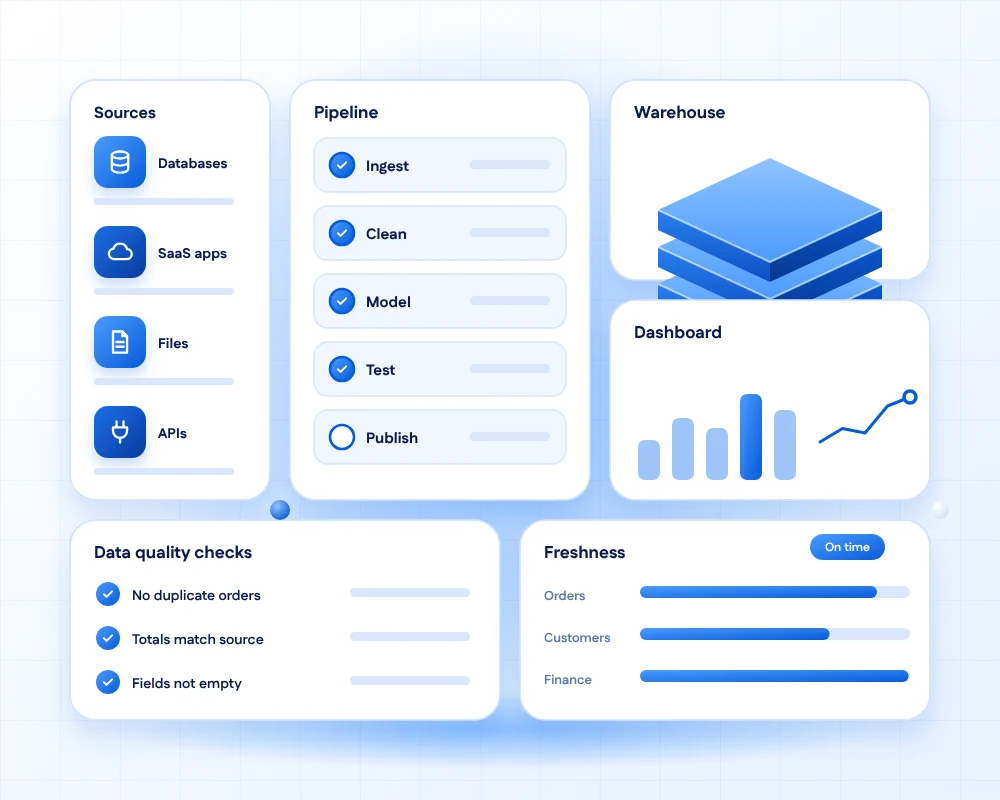
We build the pipelines, warehouse and data models that fix this, with tests and alerts so problems are found by the system, not by a manager in a meeting.
The result is one trusted source for reports, dashboards and machine learning, which your team can understand and extend.
- 11+Years of building business software
- 50+Global long-term clients
- 2,000+Projects delivered
- 24 hrsResponse time on queries
Why it matters
From scattered data to one trusted source
What changes when the foundations are right.
Before
Familiar and costly- Numbers differ between reports, and nobody is sure which is right
- Analysts spend most of their week cleaning spreadsheets
- Data arrives late or breaks without anyone noticing
- AI projects stall because the data is not ready
After
Calm and reusable- One agreed definition for each key measure
- Clean, modelled data ready for analysis and AI
- Pipelines with tests and alerts when something fails
- A platform that new reports and models build on
The platform
Five layers, each with a clear job
We build only the layers you need, in the order of value.

Ingest
Connect databases, SaaS tools, files and APIs, in batches or as events happen.
Sources
Store
A warehouse or lakehouse that holds raw and modelled data, with clear ownership.
Warehouse
Transform
Clean, join and model the data into trusted tables with version-controlled logic.
Models
Govern
Access control, lineage and quality tests so people can see where numbers come from.
Trust
Serve
Dashboards, reports, APIs and features for machine learning, all from the same source.
Insights
Services
Our Data Engineering Services
From first pipeline to a platform that scales.
Data Integration & Pipelines
Reliable, monitored flows from your systems into one place, built to recover from failures.
Data Warehouse & Lakehouse
Design and build on the platform that suits your size, skills and budget.
Analytics Engineering
Tested, documented data models that give every team the same definitions.
Dashboards & Self-Serve BI
Clear dashboards people use, and a semantic layer that lets them explore safely.

Data Quality & Observability
Automated tests and alerts on freshness, volume and accuracy, before users notice problems.

Data for AI
Prepare, label and serve data for models and for retrieval, with privacy built in.
What we measure
A platform is judged by trust
We agree these measures at the start and report on them.
How we work
From key measure to scalable platform
Five steps that deliver value early.
Agree what matters
List the decisions that need data, the key measures and who owns each definition.
RequirementsMap the sources
Inventory systems, quality and access, and decide what moves in real time or in batches.
DiscoveryBuild a thin slice
Deliver one measure end to end, from source to dashboard, with tests and documentation.
First sliceAdd controls
Access rules, lineage, quality checks and cost monitoring for the platform.
GovernanceExpand and hand over
Add sources and teams in order of value, and train your people to run and extend it.
Scale
Built to be trusted
What we verify in every pipeline
The habits that make data dependable.
- Tests on every modelUniqueness, completeness and relationship checks run before data is published.
- Alerts on freshnessLate or missing data raises an alert before the morning meeting.
- Documented definitionsEach measure has an owner and a written definition.
- LineageYou can trace any number back to its source tables.
- Access and privacySensitive fields masked, and access granted by role.
- Cost controlsBudgets and alerts on compute and storage, so the bill stays predictable.
Ready to put the data to work?
Predictive analytics turns clean data into forecasts of demand, churn and risk.
FAQs
Data engineering questions, answered
Data engineering is building the systems that collect, store, clean and deliver data so it can be analysed and used by AI. It includes pipelines, warehouses, data models, quality tests and the infrastructure that runs them.
AI and analytics are only as good as the data behind them. Most failed projects trace back to scattered, inconsistent or late data. Solid pipelines and models make every later report and model faster and more trustworthy.
A warehouse stores structured, modelled data for reporting. A lake stores raw data of any type cheaply. A lakehouse combines both ideas. We recommend one based on your data types, team skills and budget.
We work with the major cloud platforms and warehouses and with open source tools. We choose based on your existing stack, team skills, scale and cost, rather than pushing one product.
Yes. We connect CRM, ERP, eCommerce, marketing, finance and custom databases and files, using APIs, change data capture or batch loads depending on what each source supports.
We write tests for every key table, reconcile totals against source systems, document definitions with owners and alert on late or missing data, so errors are found by tests, not by executives.
Yes. We build dashboards in your preferred BI tool, and set up a shared semantic layer so that everyone uses the same definitions.
A first useful slice, one measure end to end, often takes four to eight weeks. A full platform grows over several months in order of business value.
We apply least-privilege access, masking of sensitive fields, audit logs, retention rules and region-aware storage, designed with your security and legal teams.
Yes. We start with an audit of pipelines, costs, quality and ownership, then fix the highest-risk issues first while you keep running.
Ready for data you can trust?
Tell us which reports people argue about and which systems hold the data. We will propose a first slice that delivers a trusted number in weeks.